
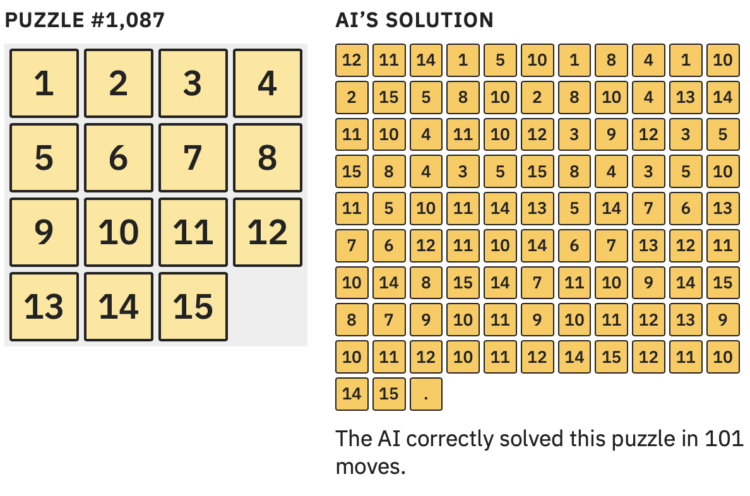
Large language models are heavily dependent on training data to determine what comes next in a series of choices. So when there is limited data for a given situation, the choices grow more uncertain. However, as Aatish Bhatia explains, this can lead to output that is “confidently wrong” instead of a highlighting random guesses.
Bhatia uses a puzzle (that you can play) to demonstrate training, processing, and the guesswork that brings you to the jagged boundary of a model’s accuracy. The boundary is surprisingly at the beginner level.
 Visualize This: The FlowingData Guide to Design, Visualization, and Statistics (2nd Edition)
